How a ComfyUI Workflow Works, and How to Run It From Python

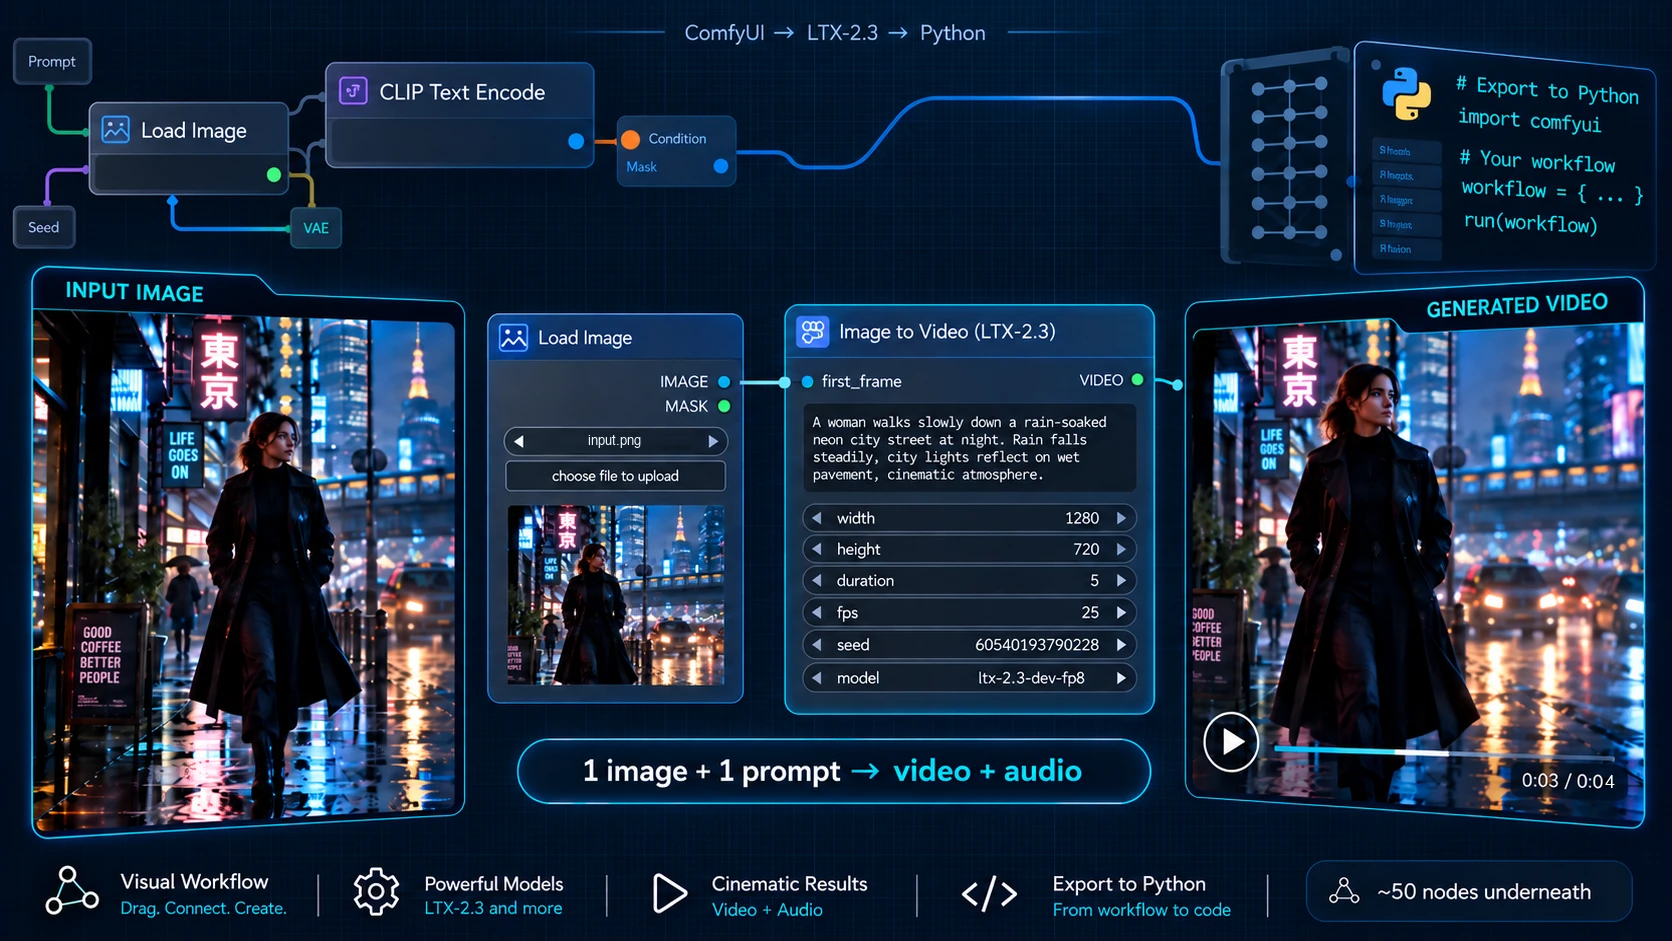
Open ComfyUI's LTX-2.3 template and you are looking at fifty nodes. Nine settings are yours to change, and the rest is wiring. This is how to tell them apart, and how to run the whole thing from Python once you want to.
Fifty nodes, nine you touch
The template opens with three boxes and a sticky note. One loads your image, one saves the video, and the middle one is the whole workflow folded up. ComfyUI calls that middle box a subgraph. Think of it as a folder: one box standing in for a whole diagram underneath, with the fifty nodes inside it.
Nine things are yours to change. Eight of them are in the folder; the ninth is your input image, which sits outside it. The other forty-two are plumbing that works as shipped.
Click the middle node below to open the folder, and drag to move around. The API export tab shows the same graph flattened into what the server actually runs.
API export flattens the subgraph. Nodes from inside the folder keep their number with the folder's in front: 319 becomes 320:319.
workflow-ui.json and workflow-api.json.Getting the workflow ready
Two things have to be in place before Run does anything.
Your image. Drag it onto the LoadImage node and the browser uploads it to the server. Everything the workflow touches lives under one directory:
/home/ComfyUI/input/     your uploads
/home/ComfyUI/output/    everything the workflow saves
/home/ComfyUI/models/    the weights
On a Jarvislabs instance /home is your volume, so those survive a pause and resume. Anything written outside them does not.
The models. A workflow stores the names of the models it needs, not the models. Open the template on a fresh machine and ComfyUI lists what is missing before it will run anything.
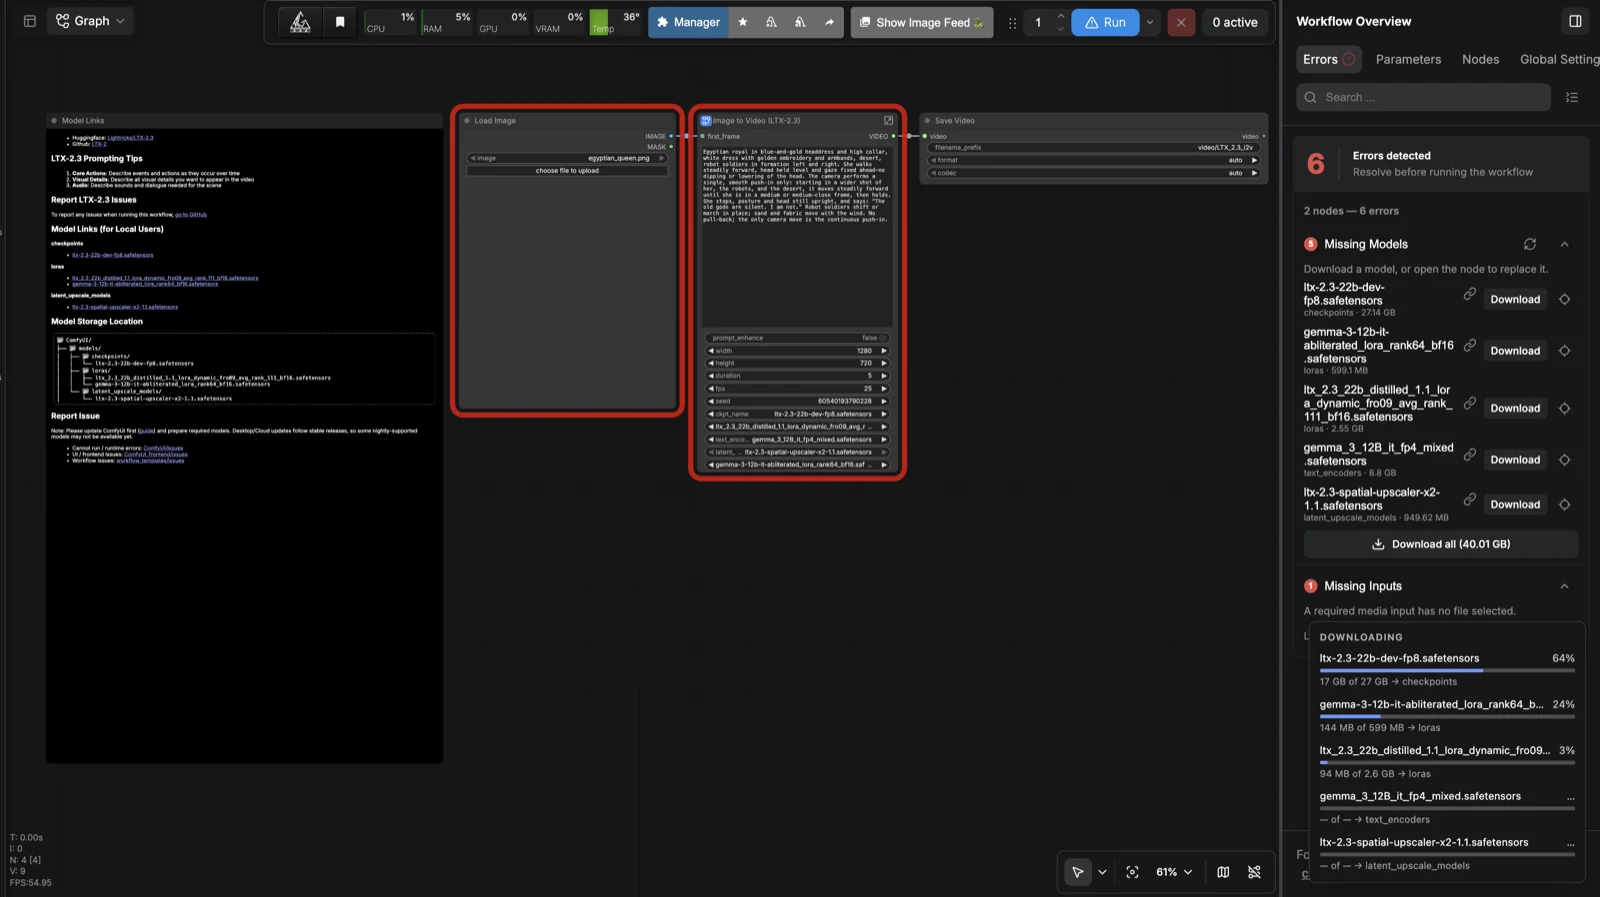
Five files, 42.97 GB, most of it one 29 GB checkpoint. They land on your volume, so you pay this once.
On a Jarvislabs instance much of this is already cached, so there is nothing to download. In future that store will hold over a hundred models.
| File | Size | What it is for |
|---|---|---|
ltx-2.3-22b-dev-fp8 | 29.15 GB | The main model. Turns noise into a picture and a soundtrack. |
gemma_3_12B_it_fp4_mixed | 9.45 GB | Reads your prompt and turns it into something the model understands. |
ltx_2.3_22b_distilled_1.1_lora | 2.74 GB | Makes it fast. Seconds instead of minutes. |
ltx-2.3-spatial-upscaler-x2-1.1 | 1.00 GB | Generates at half size and doubles it, which is cheaper than making it big from the start. |
gemma-3-12b-it-abliterated_lora | 0.63 GB | Adjusts how the prompt is read. We did not test what it changes. |
Every node here ships with ComfyUI — no custom packs, nothing to install. The models are the opposite: downloaded once, then kept on your volume.
Download lands on the GPU, not your browser. ComfyUI's missing-models dialog is an ordinary browser link, so on a rented machine it fetches tens of gigabytes to the wrong computer. On a Jarvislabs instance that fetch happens on the server instead.
The controls you actually change
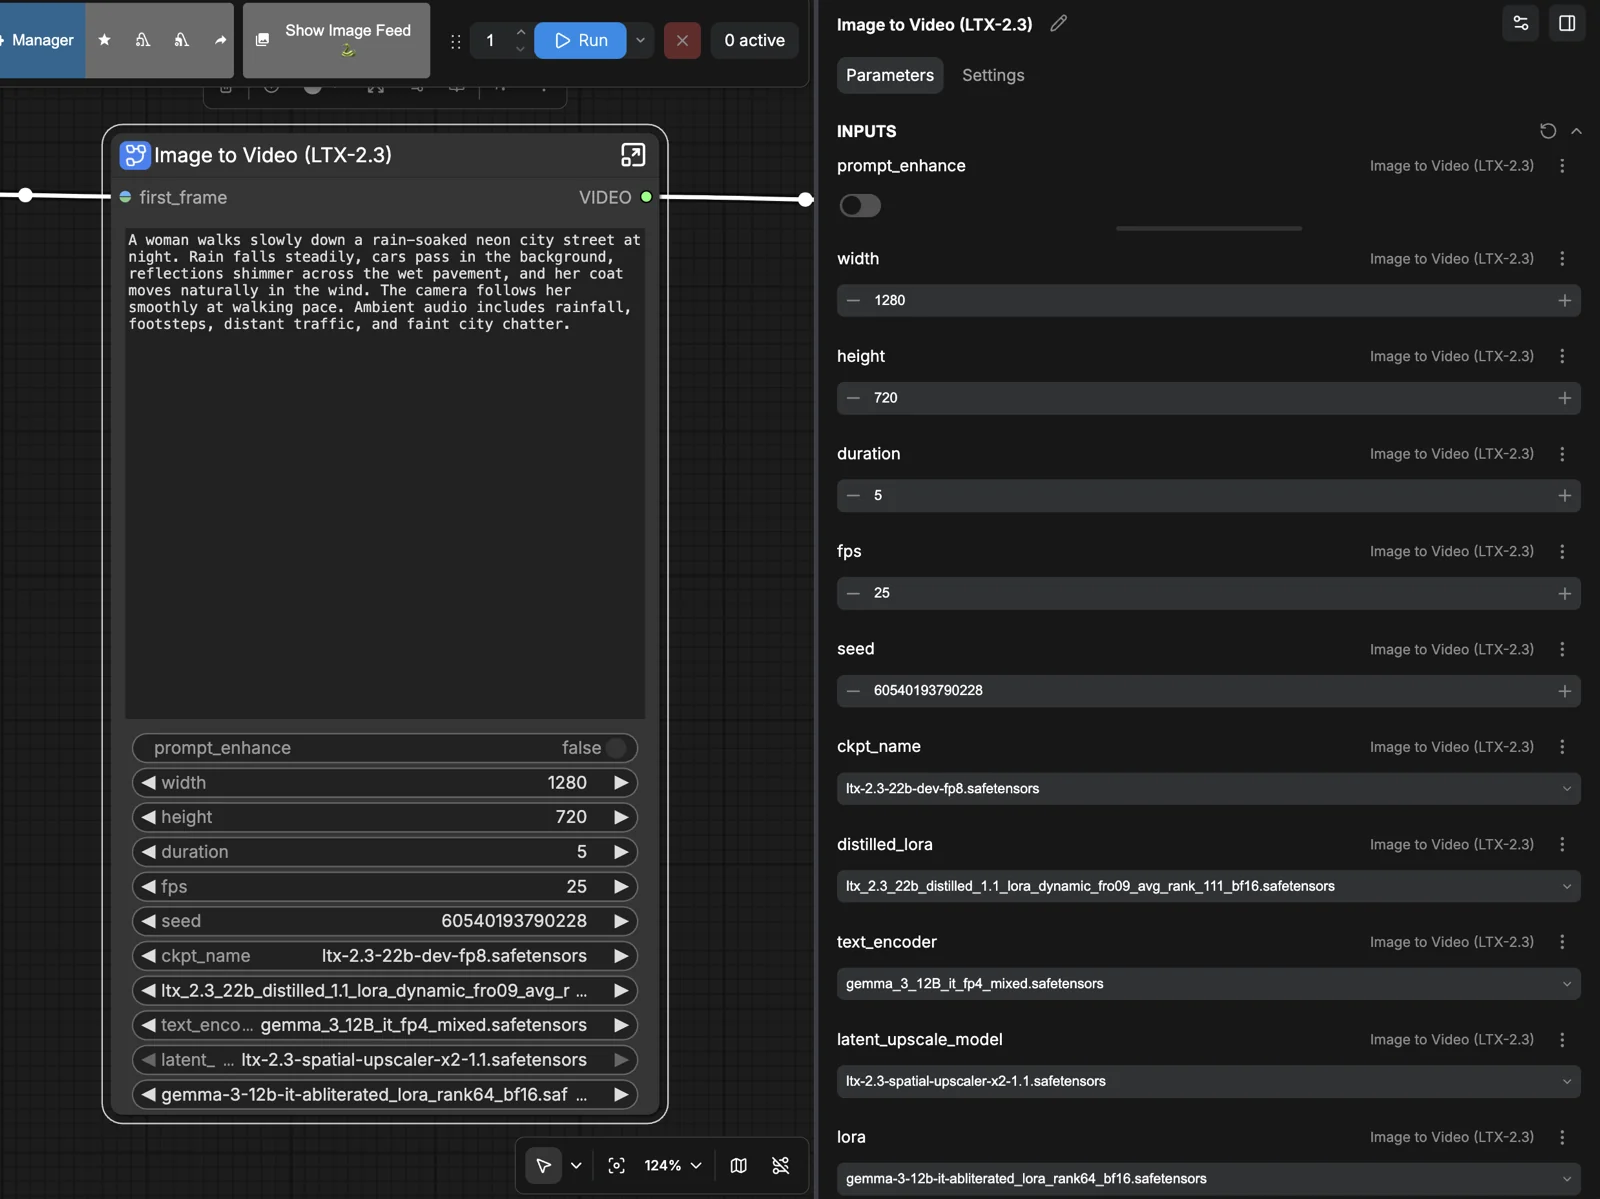
| Control | What it does |
|---|---|
| prompt | One text box, describing the picture and the sound. There is no separate audio field. |
| width / height | What you expect, with a catch. |
| duration / fps | Seconds and frames per second. You do not set a frame count; the graph multiplies these. |
| seed 1 | Decides the starting noise. Same seed and same settings gives the same video. |
| seed 2 | The workflow denoises twice, so there are two. This one is fixed at 42 and not on screen. It still changes your output, because the second pass re-noises the picture to 85% before cleaning it up again. |
| prompt enhance | Rewrites your prompt before the model sees it. We left it off, so everything here came from the sentence as typed. |
What happens when you press Run
your image  +  your prompt
        |
        v
  LTX builds picture and sound together, as one thing
        |
        v
  a second pass refines it, and doubles the size
        |
        v
  an MP4 in /home/ComfyUI/output
The forty-two nodes you are ignoring are what those four lines actually do.
With the models already loaded, each video takes 14.38 seconds — about 1.6 cents at the H200 rate at Jarvislabs.
This is what came out of it: one photograph in, five seconds of video out.
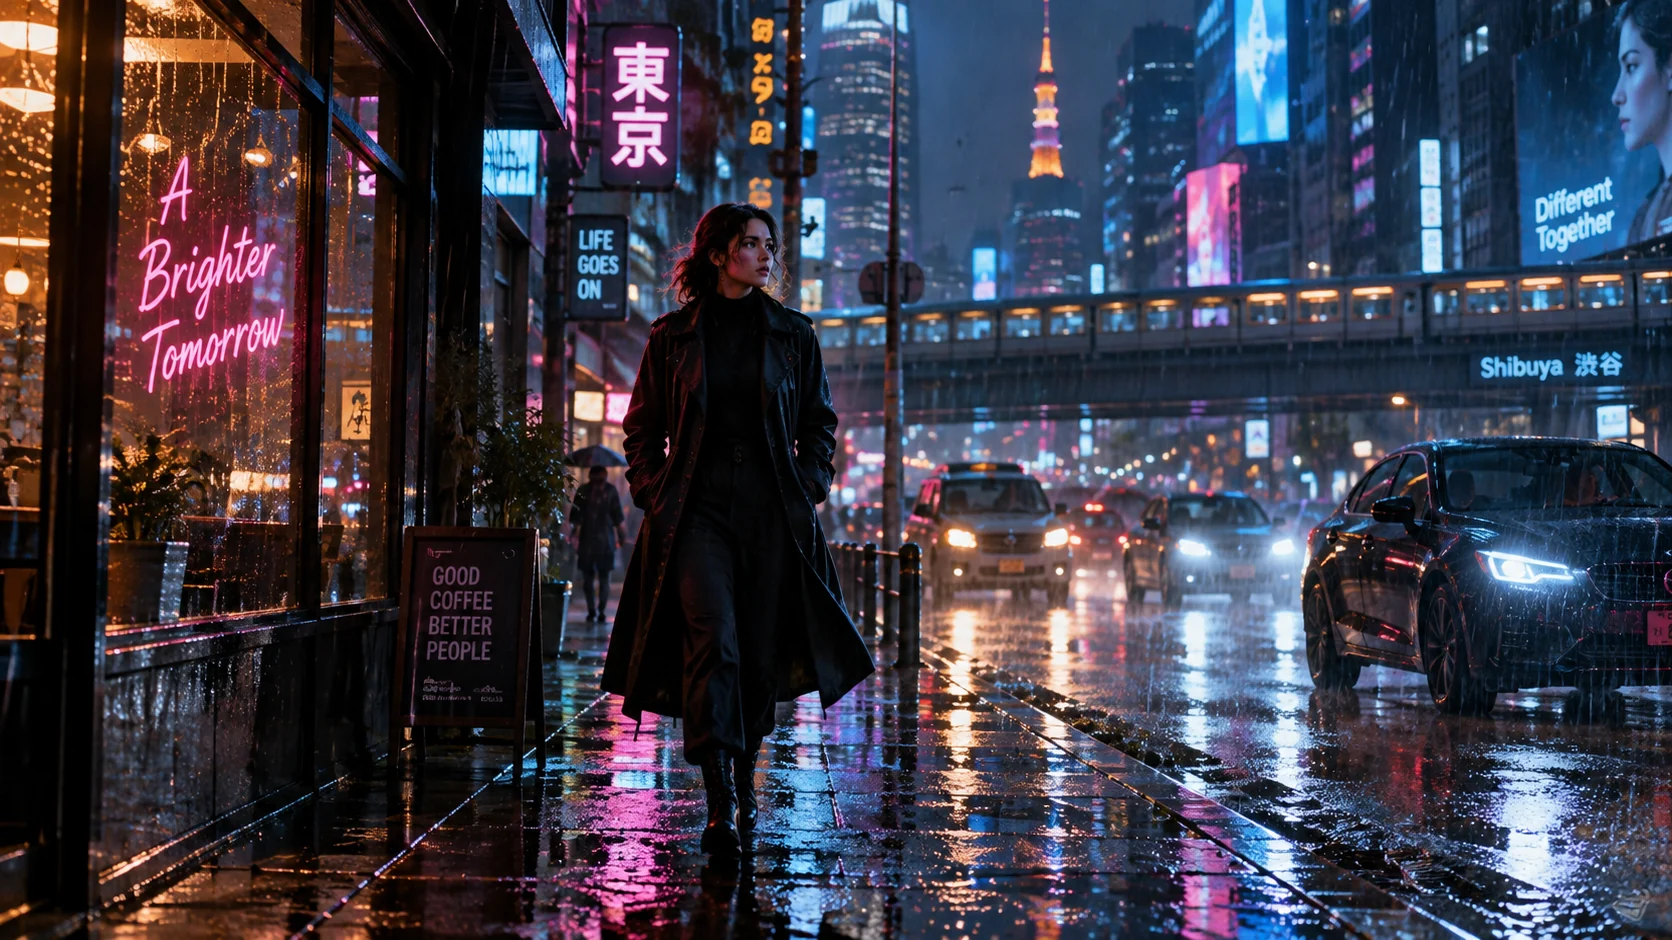
The still we started from, and the five seconds it became. Play it with sound: the rain was generated in the same pass as the picture, from the same sentence. Nothing here was filmed or recorded.
There is no separate audio model and no separate audio step. The same model builds the picture and the sound together, in one pass, from the same sentence.
Why 720 pixels became 704
Ask for a size that is not a multiple of 32 and you will not get it. This is LTX-2.3's design, not a setting we chose. The model does not work in pixels. It works on a grid, where one square is 32×32 pixels and eight frames of time, and half a square does not exist. Your numbers round down to whole squares.
width    1280 ÷ 32        = 40     ->  40 squares  ->  1280, unchanged
height   720 ÷ 32         = 22.5   ->  22 squares  ->  704 pixels
frames   5 s × 25 fps + 1 = 126    ->  15 squares  ->  121 frames

asked for   1280×720, 5.00 s   ->   got   1280×704, 4.84 s
Nothing on screen mentions it.
Why pressing Run twice gives the same video
Run it twice unchanged and you get the same video back. ComfyUI caches per node. If your graph matches one that already ran, nothing is generated — you get the earlier file back. /history reports how many nodes were skipped, under execution_cached.
what you change     it takes   and you get back
nothing              4.02 s    the same video
seed 2              10.03 s    same take, different finish
seed 1              14.38 s    a different video
prompt              16.04 s    a different video
input image         16.04 s    a different video
Building a re-roll button? Change seed 1. It picks the starting noise, so you get a genuinely different video. Seed 2 only re-rolls the refinement pass, which is the same take with a different finish. Change neither and nothing is generated at all: the cache hands back the previous video, and your user files a bug that is not one.
Running it from code
To drive it from Python you need the version the server runs. ComfyUI calls that the API export, and it is under Graph → Export (API). If the docs send you to File → Export Workflow (API), ours was under Graph.
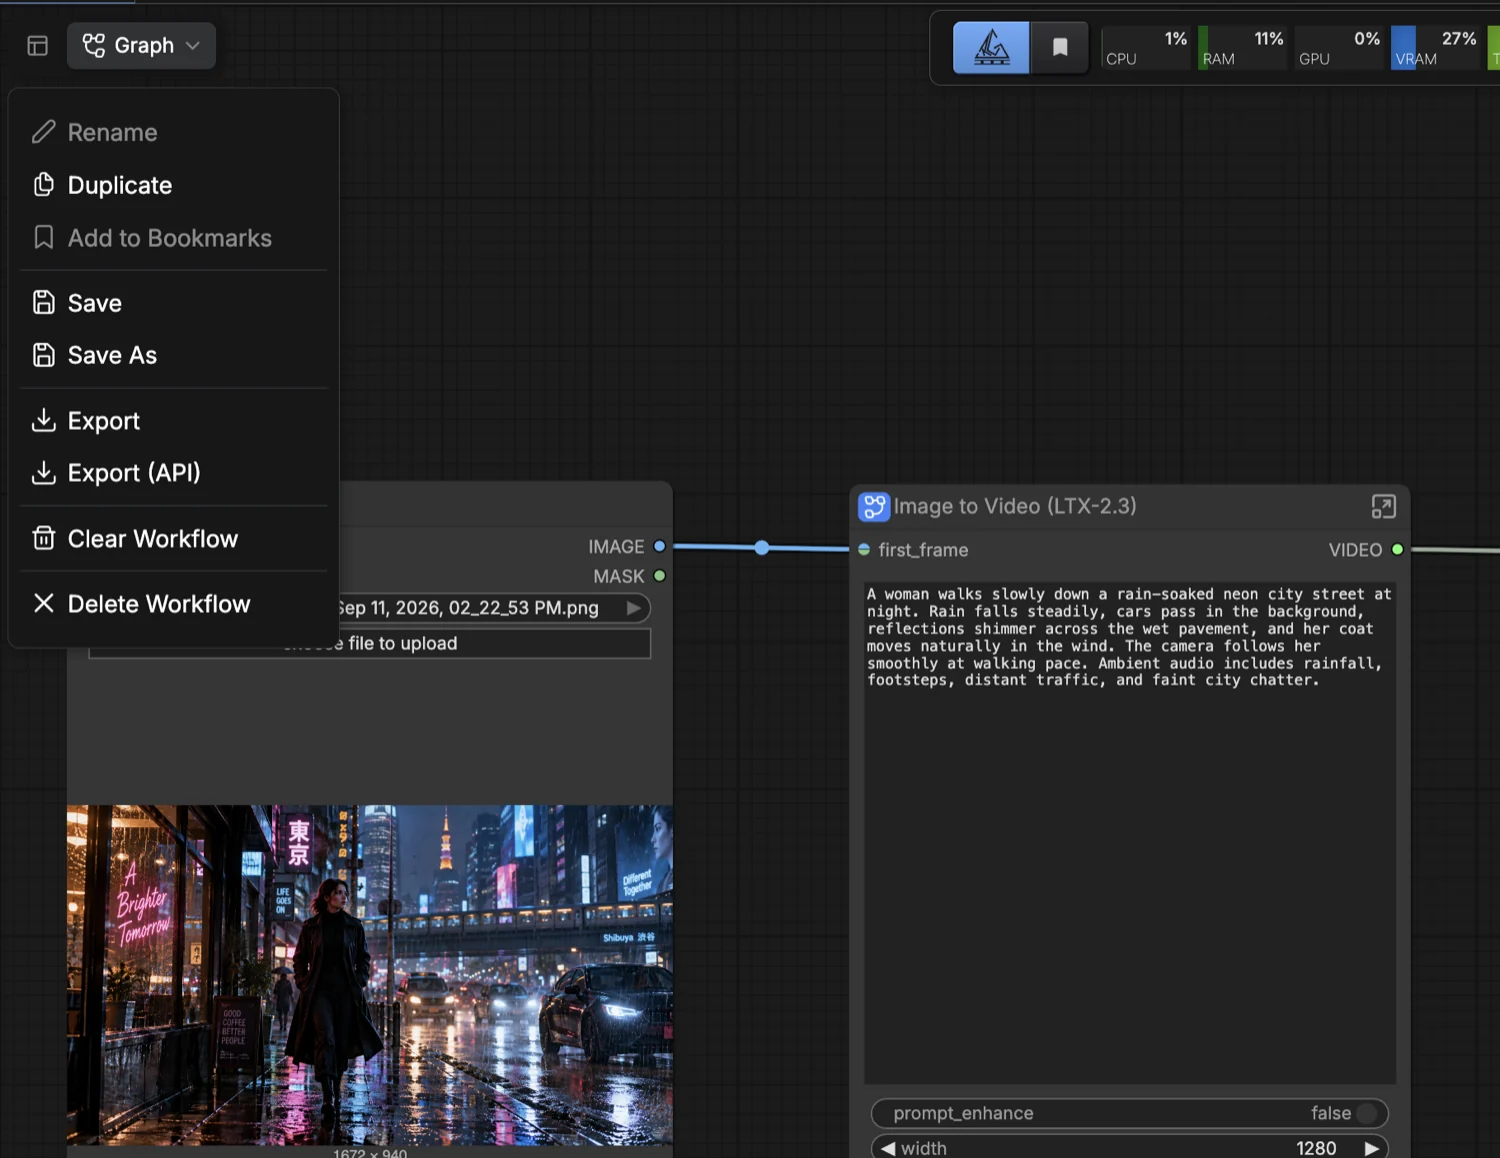
Graph → Export (API). The one next to it, plain Export, gives you the visual file instead.
It is the same workflow with everything the editor needed to draw it removed: positions, colours, notes, the subgraph boundary. That is 134 KB down to 14 KB.
The names do not survive. The editor knows that control is called
prompt. The export calls it320:319, and nothing in that string tells you what it is. So do not hand the raw export to your application. Treat it as a template, and keep a small map from readable names to ids beside it.
prompt  ->  320:319
width   ->  320:312
height  ->  320:299
image   ->  269
Those are ours. To find yours: type something distinctive into a control, export, and search the JSON for it. Each control lands on exactly one node.
Four endpoints do everything, and that block is the whole spec.
POST /upload/image      returns the name the server stored
POST /prompt            the api-format graph; returns a prompt_id
GET  /history/{id}      empty until the job finishes, then holds the outputs
GET  /view              the bytes, by filename + subfolder + type
ComfyUI on a Jarvislabs instance is behind a password. It is in /home/.jarvis_password,
and it changes every time the instance starts, so read it rather than pasting it in.
import json, time, urllib.request, urllib.error, urllib.parse
BASE = "https://<your instance URL>"
AUTH = {"Authorization": f"Bearer {PASSWORD}"}

def submit(graph):                       # POST /prompt
    r = urllib.request.Request(f"{BASE}/prompt", method="POST",
            data=json.dumps({"prompt": graph}).encode(),
            headers={**AUTH, "Content-Type": "application/json"})
    try:
        return json.load(urllib.request.urlopen(r, timeout=60))["prompt_id"]
    except urllib.error.HTTPError as e:  # names the node and the bad value
        raise RuntimeError(e.read().decode()) from None

def wait(pid, timeout=900):              # GET /history/{id}
    end = time.time() + timeout
    while time.time() < end:             # empty means "not finished", not "error"
        r = urllib.request.Request(f"{BASE}/history/{pid}", headers=AUTH)
        h = json.load(urllib.request.urlopen(r, timeout=30))
        if pid in h:
            if h[pid].get("status", {}).get("status_str") == "error":
                raise RuntimeError(h[pid]["status"])
            return h[pid]
        time.sleep(1)
    raise TimeoutError(pid)

def download(f, dest):                   # GET /view
    q = urllib.parse.urlencode({"filename":  f["filename"],
                                "subfolder": f.get("subfolder", ""),
                                "type":      f.get("type", "output")})
    r = urllib.request.Request(f"{BASE}/view?{q}", headers=AUTH)
    with urllib.request.urlopen(r, timeout=300) as resp:
        open(dest, "wb").write(resp.read())

entry = wait(submit(graph))
for f in entry["outputs"]["75"]["images"]:  # 75 is the node that saves
    download(f, f["filename"])
The history entry holds the output filenames. Fetch each one from /view, and the whole
run is four steps:
upload the image   ->  use the name the server returns
build the graph    ->  your id map, both seeds set explicitly
submit, then wait  ->  the history entry
/view each output  ->  out.mp4
Use the filename the server returns, not the one you sent. If that name already exists with different content, ComfyUI saves yours as
input (1).png. Use your own name and you run the old image.
You should not have to do any of this. A saved workflow with named inputs is the shape we think this should take:
POST /v1/deployments/{id}/run
{"prompt": "a rain-soaked neon street", "seed": 42}
No template, no node ids. It is a prototype today. If that is what you need, tell us — support@jarvislabs.ai. What people ask for is how we decide what to build.
Where to go from here
Open the template, drop in an image, type a sentence and press Run. That is the whole thing, and the nine controls above are all you need to touch.
You can launch a ComfyUI instance on Jarvislabs with the image and the model store already attached, and pause it when you are not using it.
Frequently Asked Questions About ComfyUI Workflows
Why does ComfyUI return a different resolution than the one I requested?
The model works on a 32-pixel grid, so your numbers round down. Ask for 1280×720 at five seconds and you get 1280×704 at 4.84 seconds. Nothing in the interface warns you.
Why does ComfyUI return the same video when I press Run again?
ComfyUI caches per node, so an unchanged graph hands back the previous file — 4 seconds instead of 14. A re-roll button has to change the content seed.
Does ComfyUI's API export keep the parameter names?
No. A control the editor calls prompt becomes the key 320:319, and nothing in that string says what it is. Keep your own map from names to node ids.
Do I need extra models to get audio out of LTX-2.3?
No. The sound comes out of the same 29 GB checkpoint, in the same pass, from the same prompt. LTX 2.5 adds a separate audio decoder; 2.3 does not.
Get Started
Build & Deploy Your AI in Minutes
Cloud GPU infrastructure designed specifically for AI development. Start training and deploying models today.
View Pricing